Between U+1D400 and U+1D7FF, Unicode reserves 1,024 code points for styled variants of the Latin and Greek alphabets. This is the Mathematical Alphanumeric Symbols block, and it is the entire technical basis of every italic text generator on the internet.
It exists for mathematics, not for social media. Mathematicians write an upright A and an italic A to mean different things, and a plain text equation has to preserve that difference without relying on formatting. So the difference was encoded into the characters themselves.
What the block contains
Thirteen complete Latin alphabets, each with capitals and lowercase:
| Family | Variants |
|---|---|
| Serif | Bold, italic, bold italic |
| Script | Script, bold script |
| Fraktur | Fraktur, bold fraktur |
| Double struck | One set, used for number sets like the reals and integers |
| Sans serif | Regular, bold, italic, bold italic |
| Monospace | One set |
Plus Greek in several of the same weights, and five sets of digits: bold, double struck, sans serif, sans serif bold and monospace.
Note what is missing from that digit list. Italic has no digits. Script has no digits. Fraktur has no digits. There was no mathematical convention requiring them, so they were never encoded, and no converter can produce them. That is why a year or a price stays upright in the middle of an italic phrase, which surprises almost everyone the first time they see it.
Why the arithmetic works
Within each alphabet, the letters run in order. Capital A sits at the start of the run, capital B one code point later, and so on through Z, then lowercase a follows.
That means a converter does not need a lookup table of 1,024 entries. It needs the start point of each alphabet and one piece of arithmetic: take the letter’s position in the alphabet and add it to the start point.
Italic lowercase begins at U+1D44E, so italic a is U+1D44E, italic b is U+1D44F, and italic c is U+1D44E plus two. The whole conversion is an offset.
Why the arithmetic sometimes fails
Unicode has a standing principle: never encode the same character twice.
When this block was drafted, a number of italic, script, fraktur and double struck letters had already been encoded years earlier in the Letterlike Symbols block, because physicists and mathematicians needed them individually before anyone proposed a complete set.
Rather than create duplicates, the committee left those slots permanently unassigned and pointed implementers at the existing characters. There are twenty four of these exceptions across four styles:
| Style | Letters that live elsewhere | Count |
|---|---|---|
| Italic | h | 1 |
| Script | B, E, F, H, I, L, M, R, e, g, o | 11 |
| Fraktur | C, H, I, R, Z | 5 |
| Double struck | C, H, N, P, Q, R, Z | 7 |
Italic h is not at U+1D455. That slot is unassigned, and the character you want is U+210E, the Planck constant, which happens to be drawn as an italic h.
Script is the worst affected, with eleven holes. A converter that applies pure arithmetic and ignores the exceptions produces unassigned code points for roughly a fifth of the script alphabet, and your device draws an empty box where the letter should be. The history behind those gaps is covered in why some italic letters are missing.
How the block got here
The block was encoded in 2001, and the reason is more practical than it sounds.
Mathematical notation is meaning bearing typography. An upright d and an italic d in the same equation are different objects: one might be a differential operator, the other a variable. A bold R and a double struck R mean different things again. For centuries typesetters carried that distinction because mathematics was set by hand.
Plain text broke it. Once equations moved into email, source code, databases and interchange formats, a system that stored only R lost information that the printed page had preserved. The proposal that became this block existed to put that distinction back into the character stream, so an equation could survive being copied between systems that know nothing about formatting.
That origin explains every quirk. Digits exist only where mathematics used them, which is why italic and script have none. Greek is included because Greek variables are everywhere in physics. The letters were classified as symbols rather than letters because that is what they are in the context they were designed for.
None of it was designed for a bio field. Social media borrowed a notation system, and inherited its edges.
The Greek half nobody uses
Roughly a third of the block is Greek: bold, italic, bold italic, sans serif bold and sans serif bold italic, with capitals and lowercase, plus a set of variant letterforms and the nabla and partial differential symbols in each weight.
Almost no text generator exposes it, because almost nobody wants a styled Greek alphabet for a caption. It is worth knowing it is there for one reason: if you paste Greek text into a converter and get nothing back, that is why. Most tools map only the Latin range, so Greek and Cyrillic pass through unchanged.
These are letters to Unicode and symbols to everything else
This is the part with practical consequences.
Unicode assigns every character a general category. These characters carry properties that classify them as mathematical symbols rather than letters, which is correct given what they were encoded for.
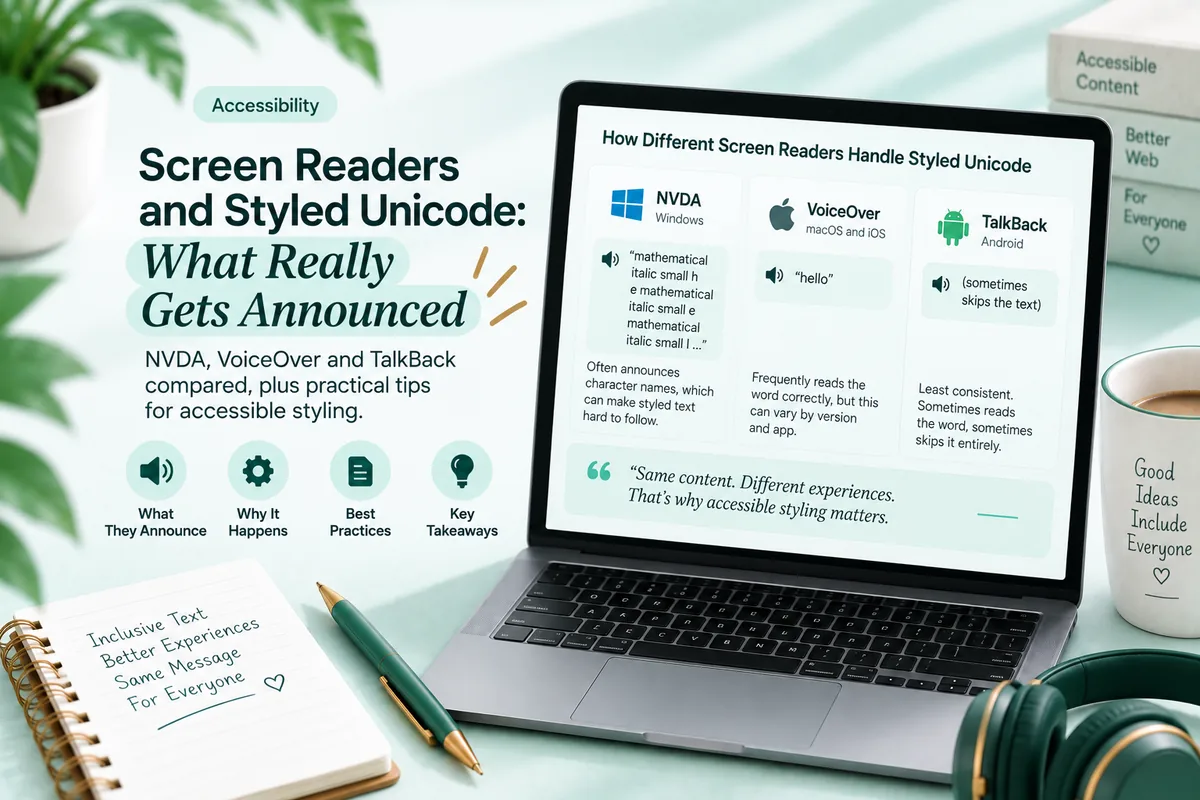
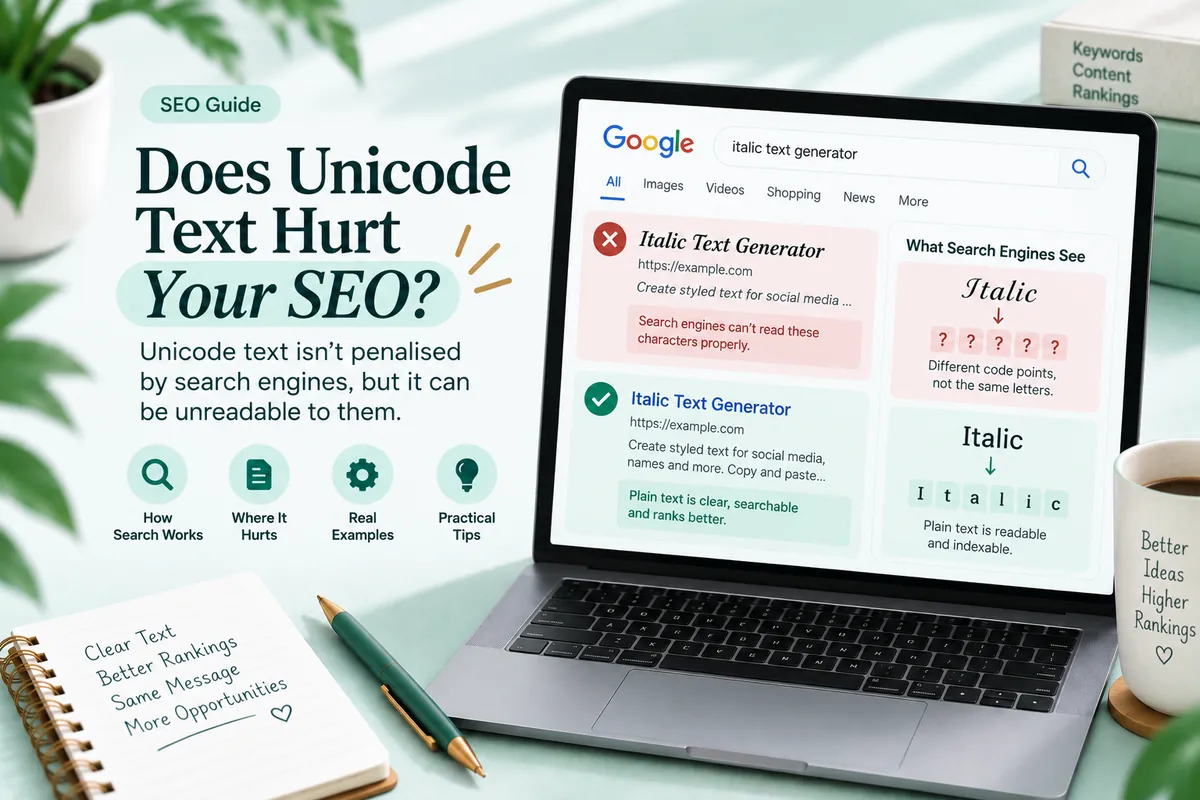
Everything downstream reads that classification. Search indexes tokenise on it, so converted words are not matched as words. Text to speech engines route on it, so a screen reader may announce character names or skip the run. Spell checkers ignore them. Sorting and case folding do not behave as you would expect.
None of that is a bug. It is the standard being used exactly as written, for text that was borrowed for a purpose it was not designed for. The search side is covered in does Unicode text hurt your SEO and the reader side in what screen readers really announce.
Not every style in a generator comes from this block
A generator typically offers more styles than this block contains, which is worth knowing when you are deciding what will render reliably.
Circled and squared letters come from Enclosed Alphanumerics and Enclosed Alphanumeric Supplement. Small caps and superscript characters come from Phonetic Extensions and Superscripts and Subscripts, and both of those sets have gaps in the alphabet, covered in the small caps and superscript guide. Fullwidth letters come from Halfwidth and Fullwidth Forms. Underline and strikethrough are not substituted letters at all, but combining marks stacked on ordinary text.
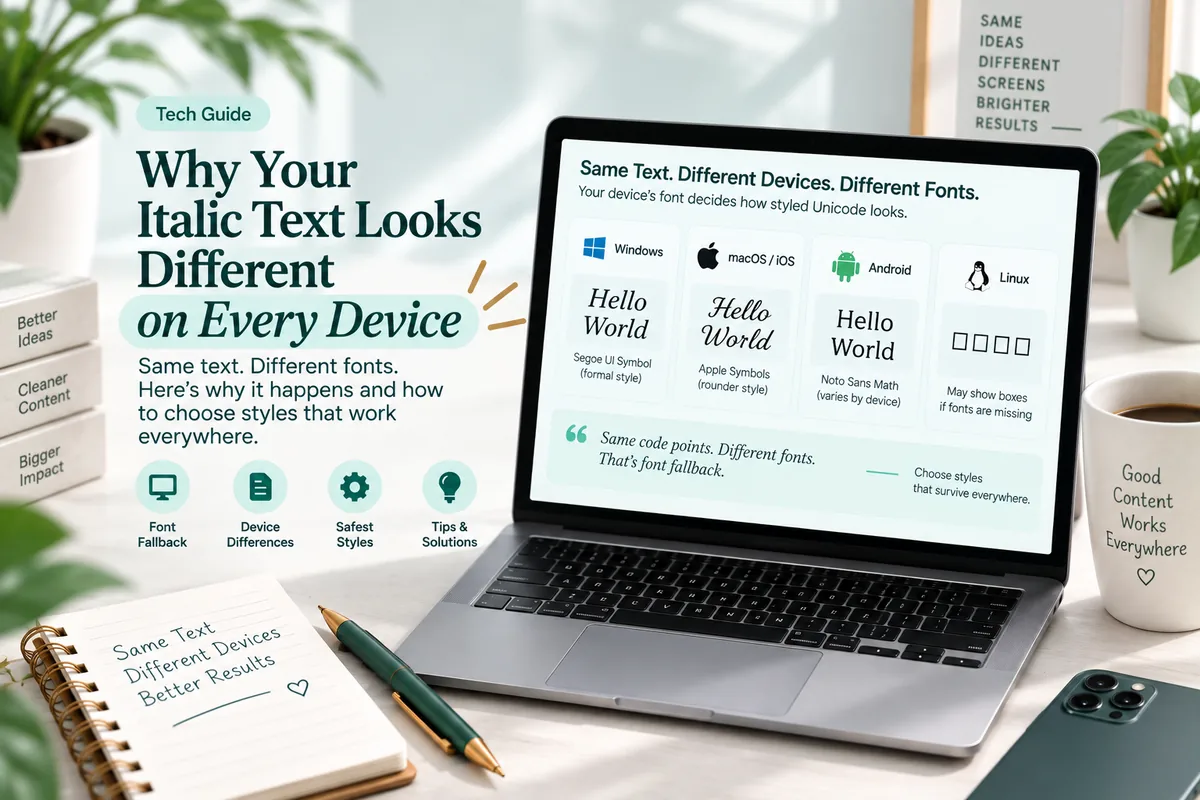
Font coverage follows those block boundaries. The mathematical block is well covered on most systems because it is old and widely used in mathematics. The enclosed forms are covered least often, which is why circled letters are the styles most likely to appear as boxes. Why italic text looks different on every device covers which fonts draw what.
Where the block sits in the wider standard
Some context that makes the rest easier to reason about.
Unicode is organised into planes of 65,536 code points each. The Basic Multilingual Plane, plane zero, holds ordinary Latin, Greek, Cyrillic, Arabic, Han and most of what people type daily. This block does not live there. It sits in plane one, the Supplementary Multilingual Plane, alongside historic scripts, musical notation and emoji.
That location has a practical consequence. Characters outside the Basic Multilingual Plane take two UTF-16 code units rather than one, which is why some systems count a single styled letter as two characters. It is also why older software occasionally mangles them: code written before supplementary planes were common assumed one unit per character.
If a platform’s character counter disagrees with what you can see, this is almost always why.
How to check a converter against the block
You do not need to read the standard to test a tool.
- Convert the word
helloto italic. Thehshould be slanted. If it is upright, the tool skipped the U+210E exception. - Convert
biggerto script. If any letters are blank boxes, it is emitting unassigned code points. - Convert
2026to italic. The digits should stay upright, because italic digits do not exist. A tool that produces slanted digits is substituting from a different style and lying about what you asked for. - Convert
2026to bold. Now the digits should change, because bold digits do exist. - Copy the result into a plain text editor and confirm it survives. Characters survive; formatting does not.
Test three is the one that separates honest tools from careless ones. The correct behaviour is to leave the digits alone.
Questions people ask about the block
What is the Mathematical Alphanumeric Symbols block? A Unicode block from U+1D400 to U+1D7FF encoding styled Latin and Greek alphabets plus five digit sets, so plain text mathematics can distinguish an upright variable from an italic one.
Why do italic and script have no digits? Because mathematics never needed them. Only bold, double struck, sans serif, sans serif bold and monospace digits were encoded.
Are these a font? No. They are characters. A font draws them, but the style difference is in the character, which is why it survives copy and paste into a plain text field.
Why do some letters come from elsewhere? Unicode does not duplicate characters. Twenty four letters already existed in Letterlike Symbols, so their slots here were left unassigned.
How many characters are in the block? The range reserves 1,024 code points, and the slots left for the earlier characters are permanently unassigned.
Why knowing this changes how you use it
These characters are letters to Unicode and symbols to almost every other system. They are not a font, they cannot be searched as words, and no amount of styling will change that, because the property that causes it is baked into the standard.
Knowing which block your text comes from is the difference between using it deliberately and being surprised by it. You can see the block’s structure, including which letters are patched by hand, in the Italic Text Generator, where every coverage figure on the page is counted from the converter’s own mapping tables.